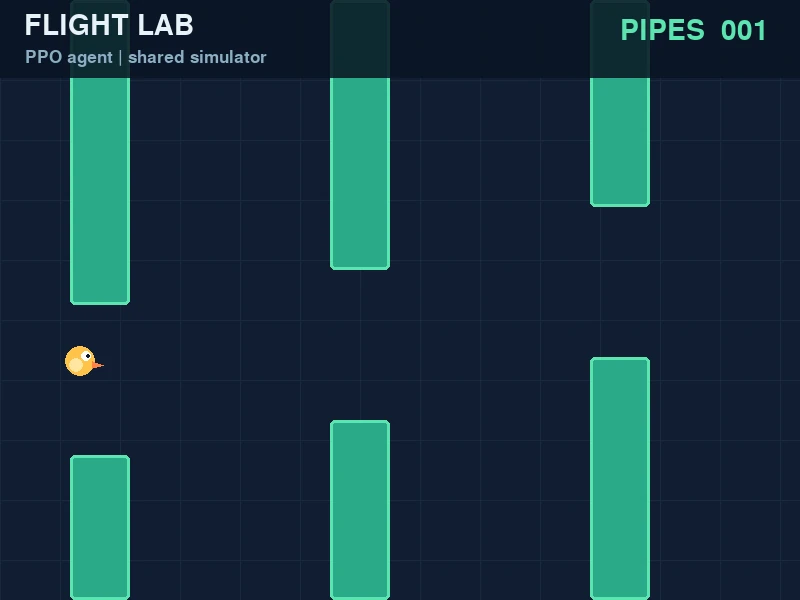
Project gameplay: Prashanna Tiwari · MIT · Resized and converted to WebP.
Created by Prashanna Tiwari.
Learning when to flap
The current implementation trains a Proximal Policy Optimization agent using a shared Gymnasium environment. Manual play, AI playback and training use the same physics, scoring and collision rules. PyTorch actor and critic networks learn from structured game observations.
The project includes three trained policies, training histories, held-out evaluation courses, baseline controllers and a mathematical report. The bundled greedy policy’s repository evaluation reports an average of 67.73 pipes on 30 courses with a 6,000-frame limit; this finite-horizon result does not guarantee indefinite play.
All 15 project tests passed during review, including environment behavior, PPO updates, checkpoint loading and the command-line workflow. A headless AI playback check and a short checkpoint evaluation also ran.
The repository retains its original flappy-bird-dqn name. Double DQN code and weights are preserved in the legacy directory; the current showcase and gameplay cover feature PPO.
Contributors
- Prashanna Tiwari
Resources & links