Repository figure: Pitambar Lamichhane (pirmber) · Repository image · Resized and converted to WebP.
Created by Pitambar Lamichhane.
Understanding how a Transformer learns
This educational decoder-only language model implements token and position embeddings, causal multi-head attention, LayerNorm, residual connections, a GELU feed-forward network and cross-entropy loss directly in NumPy. Analytical gradients and an Adam optimizer are implemented by hand.
The repository includes finite-difference gradient checks, a training pipeline, temperature and top-k sampling, and plots of loss, attention and gradient norms. It uses a small character-level corpus and CPU computation to make the mathematics inspectable.
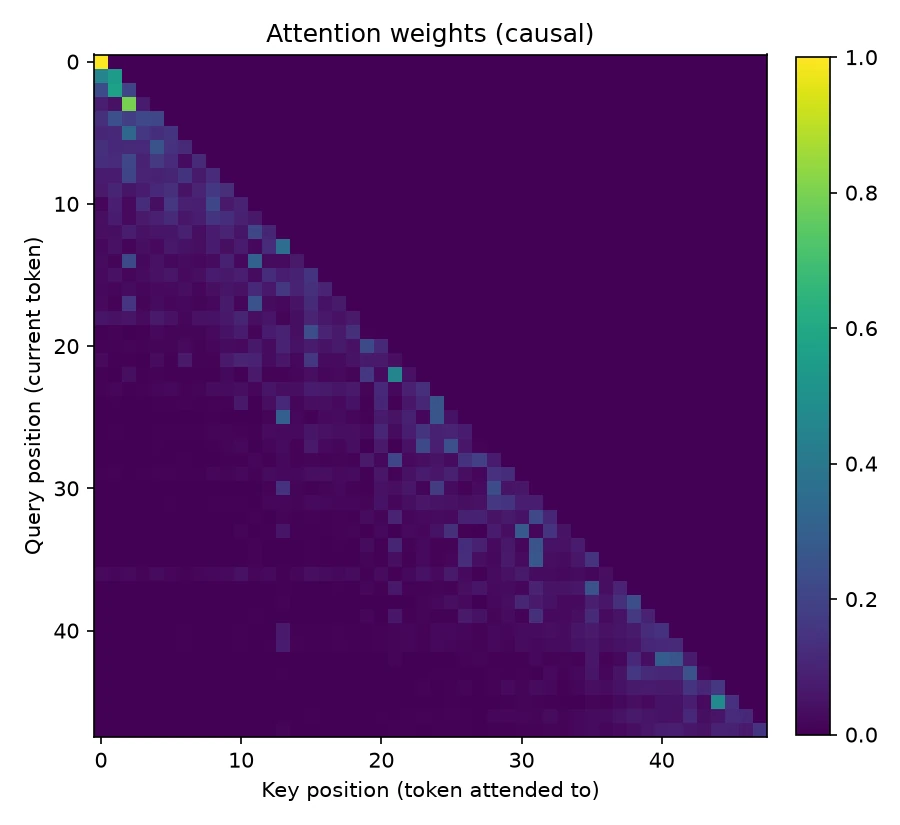
The cover is the repository’s causal-attention heatmap.
Contributors
- Pitambar Lamichhane